Carlo Otto · 22 October 2026
Optimizing query caching layers for multi-region data consistency in collaborative development environments
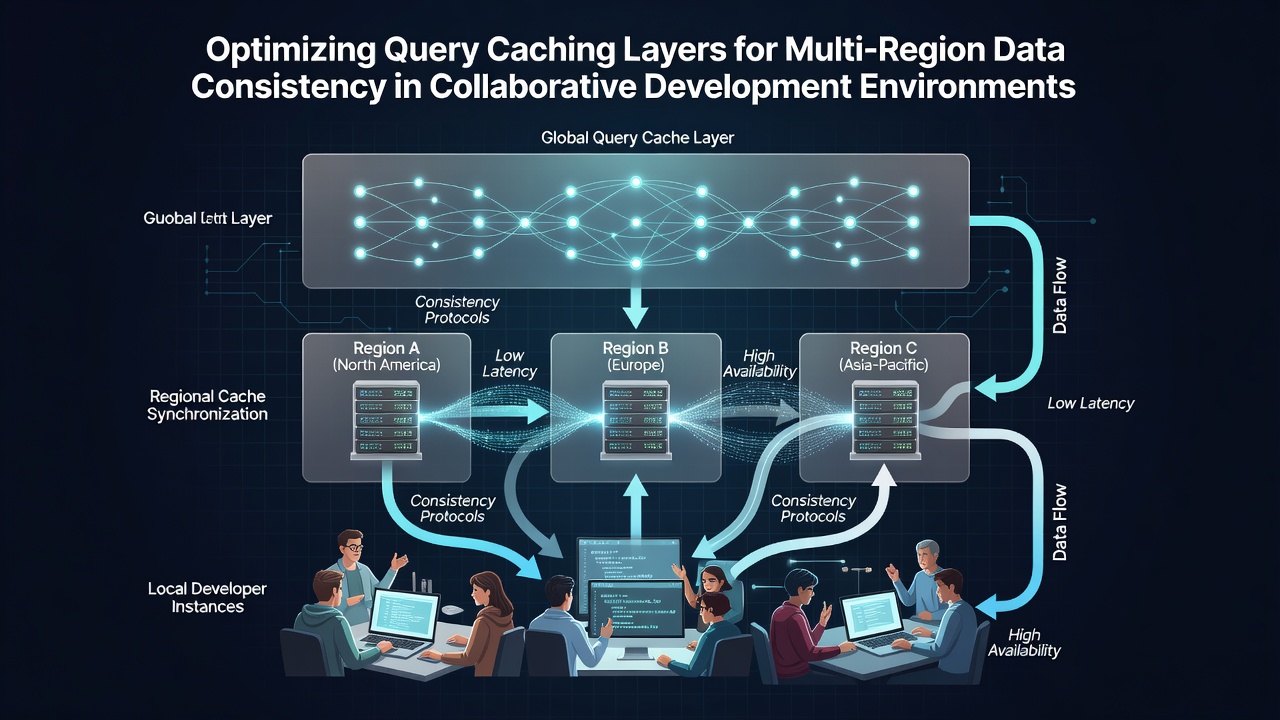
Developers working across distributed teams rely on query caching layers to reduce latency while maintaining data integrity, and these systems become particularly complex when operations span multiple geographic regions. Research indicates that effective optimization involves balancing cache hit rates against consistency guarantees, with studies showing that multi-region setups can achieve sub-100 millisecond response times when invalidation protocols align with replication schedules.
Core Mechanisms of Query Caching in Distributed Environments
Query caching layers store results from database queries at intermediate points to minimize repeated fetches from primary sources, yet in collaborative development environments where multiple contributors edit shared codebases and datasets simultaneously, the challenge centers on propagating updates without introducing stale reads. Observers note that techniques such as time-to-live expiration combined with event-driven invalidation allow caches to refresh selectively, and data from industry reports reveal that this approach cuts network traffic by up to 60 percent in setups involving teams on different continents.
Consistency models range from eventual to strong, with the former suiting many development workflows because it tolerates brief divergences while replication catches up. Researchers at institutions across North America and Europe have documented how write-through caching ensures immediate synchronization to backing stores, whereas write-behind strategies defer updates to batch operations that reduce load during peak collaboration hours.
Challenges Posed by Multi-Region Deployments
Latency variations between regions create uneven cache states, and when one team in Asia commits changes that another group in Europe must access, propagation delays can lead to conflicts if caching layers do not coordinate through consensus protocols. Figures from recent analyses show that network partitions occur in approximately 2 percent of multi-region operations, prompting engineers to implement quorum-based reads that require agreement from a majority of nodes before serving cached data.
Collaborative platforms often integrate version control systems with real-time databases, which adds another layer where query results must reflect both code and data changes. In October 2026, presentations at international conferences highlighted case studies from Australian research groups demonstrating how region-specific cache warming routines preemptively load anticipated queries based on historical access patterns, thereby improving hit rates without compromising consistency across borders.
Optimization Strategies and Implementation Patterns
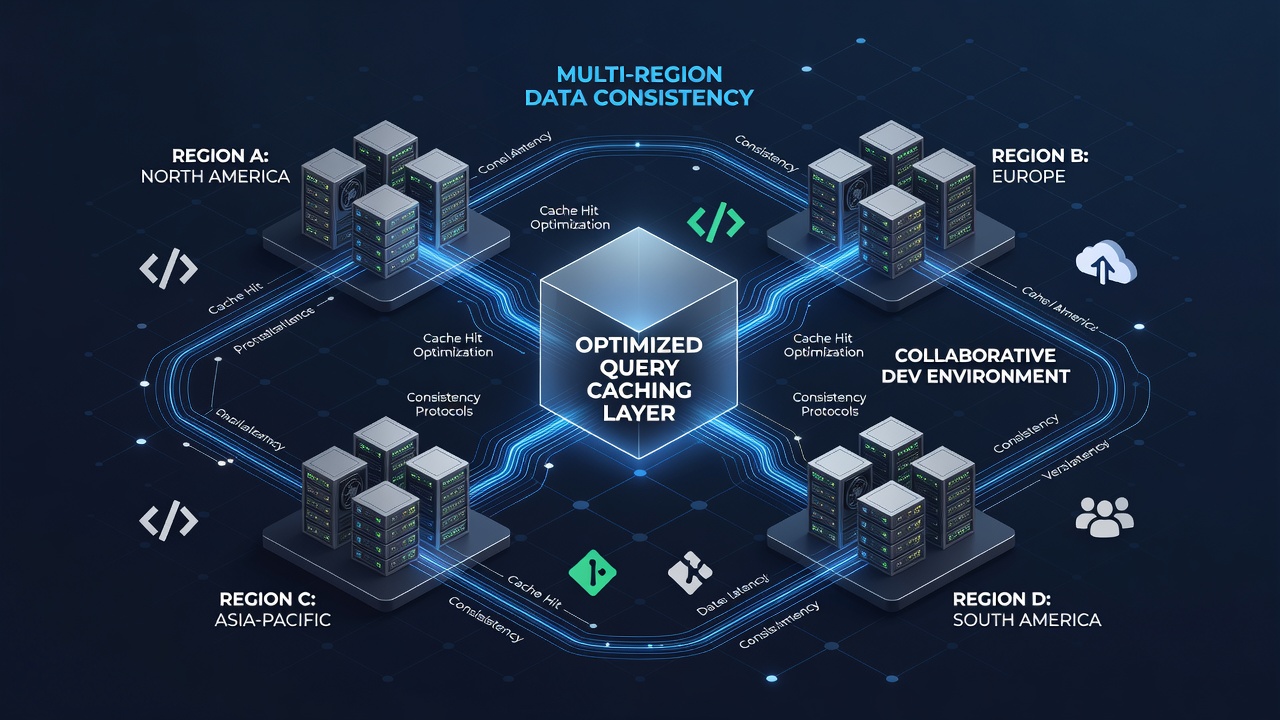
Partitioning caches by data locality allows each region to maintain copies of frequently accessed items while routing cross-region queries through dedicated synchronization channels, and experts have observed that this reduces overall bandwidth consumption. Tools supporting distributed tracing help identify hotspots where cache misses cluster, enabling targeted adjustments such as increasing replica counts in high-traffic zones.
Hybrid approaches that combine in-memory caches with persistent stores provide durability during node failures, while monitoring frameworks track metrics like staleness duration and eviction frequency. According to findings published by the National Institute of Standards and Technology, standardized benchmarks for consistency under load assist teams in selecting parameters that align with their development velocity requirements.
Automated scaling of cache instances responds to usage spikes during collaborative sprints, and integration with container orchestration platforms ensures that new nodes inherit appropriate cache configurations upon deployment. A report from the European Research Council further details how machine learning models trained on query logs can predict invalidation needs, leading to proactive refreshes that maintain data alignment without constant polling.
Case Examples from Development Teams
One documented implementation involved a software firm coordinating developers in three time zones, where initial caching setups suffered from frequent inconsistencies until they adopted a gossip protocol for propagating invalidation messages. Subsequent measurements indicated a 40 percent drop in conflict resolution time, allowing merges to proceed more smoothly.
Another scenario featured an open-source project that layered regional caches atop a global database cluster, using region tags to direct queries and enforce eventual consistency windows of under five seconds. Those who studied the deployment noted that periodic reconciliation jobs prevented drift accumulation over extended periods of parallel editing.
Conclusion
Optimizing query caching layers for multi-region data consistency requires coordinated application of expiration policies, invalidation mechanisms, and monitoring practices that adapt to the rhythms of collaborative development. Evidence from multiple regions continues to guide refinements, supporting environments where distributed teams maintain both speed and accuracy in shared workflows.